Peijie Dong 董佩杰
PhD candidate at HKUST (Guangzhou) · Expected graduation: 2027 · Open to full-time opportunities
I am Peijie Dong (董佩杰), a final-year Ph.D. candidate in the Data Science and Analytics Thrust at the Hong Kong University of Science and Technology (Guangzhou), with expected graduation in 2027, advised by Prof. Xiaowen Chu and Prof. Junxian He. I am currently a research intern with the WorkBuddy/CodeBuddy Coding Agent team at Tencent CSIG, where I work on post-training and evaluation for long-horizon coding agents.
Open to full-time opportunities · 2027 graduate
I am currently seeking full-time opportunities through the fall recruitment cycle. Please feel free to contact me at dongpeijie98@gmail.com for relevant opportunities or referrals.
正在参加秋招,预计 2027 年博士毕业。 欢迎交流全职岗位机会或内推,可通过上述邮箱联系我。
Research Interests
My research focuses on improving the ability of coding agents to solve long-horizon, repository-level software engineering tasks. I am particularly interested in transforming interaction trajectories and environment feedback into effective training signals. My current research interests include:
- Coding Agent Post-Training: Developing data and training recipes for coding agents, including trajectory curation, supervised fine-tuning, reinforcement learning, and reward design.
- Long-Horizon Agent Evaluation: Building benchmarks and agent harnesses to study planning, tool use, repository navigation, error recovery, and end-to-end task completion.
- Agent Data and Training-Evaluation Loops: Diagnosing behavioral failures from agent trajectories and translating them into targeted data, objectives, and evaluation signals.
- Efficient Large Language Models: Improving the efficiency of LLM training and inference through model compression, low-precision training, efficient architectures, and systems optimization.
My long-term goal is to build coding agents that can learn from complete interaction trajectories and reliably improve through real-world task feedback. I welcome discussions and collaborations on coding agents, post-training, evaluation, and efficient LLMs.
🔥 News
-
🎉🎉 I’ve been invited to serve on the Program Committee (PC) of the 36th International Joint Conference on Artificial Intelligence (IJCAI).
-
🎉🎉 Our paper “CPA: Efficient and Stable FP4 RL Training via Cross-Precision Alignment” is accepted by NeurIPS 2026.
-
🎉🎉 Our paper “Architecture-Aware Reinforcement Learning Makes Sliding-Window Attention Competitive in Math Reasoning” is accepted by EMNLP 2026 Main Conference.
-
🎉🎉 Our tech report “Tencent WorkBuddy Bench: A Multi-Domain Coding-Agent Benchmark with Contamination-Resistant Task Construction” is released to Arxiv.
-
🎉🎉 Our paper “An Empirical Study of Reasoning Degradation in Quantized Multimodal Large Language Models” is accepted by ACM MM 2026.
-
🎉🎉 Our paper “GreenMoE: Exploiting Dynamic Load Imbalance for Energy-Efficient Long-Context MoE Training” is accepted by ICML 2026 AdaptFM Workshop.
Earlier news
-
🎉🎉 Our paper “Parameters as Agentic Memory: Internalizing Long-Horizon Memories for Efficient LLM Agents” is accepted by ICML 2026 AIWILD Workshop.
-
🎉🎉 Our paper “Enhancing Knowledge Injection with Surrounding Backgrounds in Continual Training LLMs” is accepted by ICML 2026 FoGen Workshop.
-
🎉🎉 Our paper “Semantic Integrity Matters: Benchmarking and Preserving High-Density Reasoning in KV Cache Compression” is accepted by ICML 2026.
-
🎉🎉 Our paper “VCG-Bench: Towards A Unified Visual-Centric Benchmark for Structured Generation and Editing” is accepted by ICML 2026.
-
🎉🎉 Our paper “Identifying and Mitigating Errors in Gradient Aggregation of Distributed Data Parallel Training” is accepted by ICML 2026.
-
🎉🎉 Our Paper “Smooth Reading: Bridging the Gap of Recurrent LLM to Self-Attention LLM on Long-Context Understanding” is accepted by ICLR2026.
-
🎉🎉 Two years after graduation, I was selected as an outstanding master’s student at the NUDT in Hunan Province.
-
🎉🎉 Our Paper “ChunkKV: Semantic-Preserving KV Cache Compression for Efficient Long-Context LLM Inference” is accepted by NeurIPS 2025.
-
🎉🎉 Our Paper “Perovskite-LLM: Knowledge-Enhanced Large Language Models for Perovskite Solar Cell Research” is accepted by EMNLP 2025 findings.
-
🎉🎉 Our Paper “Smooth Reading: Bridging the Gap of Recurrent LLM to Self-Attention LLM on Long-Context Tasks” is released to arxiv.
-
🎉🎉 Our tech report “Intern-S1: A Scientific Multimodal Foundation Model” is released to arxiv. Great work by Intern-S1 team.
-
🎉🎉 Our Paper “Can Compressed LLMs Truly Act? An Empirical Evaluation of Agentic Capabilities in LLM Compresssion” is accepted by ICML25. We are especially grateful to the reviewer who awarded us a ‘5 (Strong Accept)’.
-
🎉🎉 I’ve been invited to be an Area Chair in NeurIPS 2025.
-
🎉🎉 Congratulations to our team (lead by @Ruibo) to get “SpInfer: Leveraging Low-Level Sparsity for Efficient Large Language Model Inference on GPUs” accepted by EuroSys 2025 as Best Paper !!!
-
🎉🎉 I am awarded the Excellent Research Prize for the 2024 DSA Excellent Research Award!!!
-
🎉🎉 Our STBLLM is accepted by ICLR25. STBLLM: Breaking the 1-Bit Barrier with Structured Binary LLMs, International Conference on Learning Representations, 2025.
-
🎉🎉 Our Lottery LLM Hypothesis is accepted by ICLR25 Blogpost Oral. The Lottery LLM Hypothesis, Rethinking What Abilities Should LLM Compression Preserve?, International Conference on Learning Representations Blog Track Oral, 2025.
-
🎉🎉 Our ParZC is accepted by AAA25 (Oral). ParZC: Parametric Zero-Cost Proxies for Efficient NAS, Association for the Advancement of Artificial Intelligence, 2025.
-
🎉🎉 I was invited to give a talk to PDL about “Introduction to LLM Compression and Beyond”.
-
🎉🎉 FuseFL is accepted by NeurIPS 2024 (Spotlight). FuseFL: One-Shot Federated Learning through the Lens of Causality with Progressive Layer Fusion, Neural Information Processing Systems (NeurIPS) Spotlight, 2024.
-
🎉🎉 DSA is accepted by NeurIPS 2024, Discovering Sparsity Allocation for Layer-wise Pruning of Large Language Models, Neural Information Processing Systems (NeurIPS), 2024.
-
🎉🎉 Our paper “Should we really edit language models? on the evaluation of edited language models” is accepted by NeurIPS 2024.
-
🎉🎉 LPZero is accepted by EMNLP 2024. LPZero: Language Model Zero-cost Proxy Search from Zero, Empirical Methods in Natural Language Processing (EMNLP), 2024. (paper, code)
-
🎉🎉 LongGenBench is accepted by EMNLP 2024. LongGenBench: Long-context Generation Benchmark, Empirical Methods in Natural Language Processing (EMNLP), 2024.
-
🎉🎉 Pruner-Zero is accepted by ICML 2024. This work evolves symbolic pruning metrics from scratch for large language models. (paper, code)
-
🎉🎉 VMRNN is available. This work proposes the VMRNN cell, a new recurrent unit that integrates the strengths of Vision Mamba blocks with LSTM. We construct a network centered on VMRNN cells to tackle spatiotemporal prediction tasks effectively. (paper, code)
-
🎉🎉 KD-Zero is accepted by NeurIPS 2023. This work evolves knowledge distiller for any teacher-student pairs. (paper)
-
🎉🎉 EMQ is accepted by ICCV 2023. This work evolves training-free proxies for automated mixed precision quantization. (paper, code)
-
🎉🎉 AutoKD: Automated KD via MCTS is accepted by ICCV 2023. This work proposes automated knowledge distillation via Monte Carlo Tree Search. (paper)
-
🎉🎉 DisWOT is accepted by CVPR 2023. This work proposes student architecture search for distillation without training. (paper, code)
-
🎉🎉 Progressive Meta-Pooling Learning is accepted by ICASSP 2023. This work proposes a lightweight image classification model. (paper)
-
🎉🎉 RD-NAS is accepted by ICASSP 2023. This work enhances one-shot supernet ranking ability via ranking distillation. (paper)
-
🎉🎉 AutoRF is accepted by MMM 2022. This work proposes auto learning receptive fields with spatial pooling. (paper)
-
🎉🎉 Prior-Guided One-shot NAS is accepted by CVPR Workshop 2022. This work proposes prior-guided one-shot neural architecture search. (paper)
📖 Educations
-
2023.09 - now, The Hong Kong University of Science and Technology (Guangzhou), PhD Candidate in Computer Science
- Expected Graduation: 2027
- Supervisor: Prof. Xiaowen Chu
- Research Interests: Large Language Models, Model Compression
-
2020.09 - 2023.06, National University of Defence Technology, Master of Engineering
- Supervisor: Prof. Xin Niu
- Research Interests: AutoML, Neural Architecture Search
- Achievement: Outstanding Graduate
-
2016.09 - 2020.06, Northwest Agriculture & Forestry University, B.S. in Software Engineering
- GPA: 3.78/4.0 (Ranked 1st out of 93)
- Advisor: Prof. Hongming Zhang
- Achievements: National Scholarship, Principal’s Scholarship, Outstanding Graduate
- Research Interests: Object Detection, Multi-Object Tracking
💻 Internship
- 06/2026-present: Research Intern, Tencent CSIG WorkBuddy/CodeBuddy - post-training and evaluation for long-horizon coding agents
- 10/2025–02/2026: Intern, Alibaba – large-scale model training
- 03/2025–08/2025: Intern, Shanghai AI Lab – AI infrastructure for Xtuner project
- 05/2022–08/2022: Intern, Shanghai AI Lab – model compression with MMRazor
👔 Professional Activities
- 2022: ICASSP
- 2023: NeurIPS, ICASSP, CIM
- 2024:
- Conferences: NeurIPS, ICLR, CVPR, ECCV, ICASSP, ACL (ARR)
- Journals: TPAMI, Neural Networks, Information Fusion, CIM
- 2025:
- Conferences: NeurIPS (AC), ICLR, CVPR, ECCV, ICASSP
- Journals: IJCV, Neural Networks
- 2026:
- Conferences: AAAI (PC), IJCAI (PC), WACV, NeurIPS, ICLR
- Journals: Neural Networks
🎖 Honors and Awards
- 2024, Best Speaker in DSA Salon 2024.
- 2023, Outstanding Graduate at School Level, National University of Defense Technology.
- 2022, 1st Place, BDCI Retail Product Recognition based on MindSpore (CCF Big Data & Computing Intelligence Contest).
- 2022, 1st Place, DCIC Intelligent Ship Detection Competition (Digital China Innovation Contest).
- 2022, 2nd Place, DCIC Intelligent Cattle Segmentation Competition (Digital China Innovation Contest).
- 2022, 1st Place, Baidu AI Competition - Blurred Document Image Recovery.
- 2022, 3rd Place, Computer Vision and Pattern Recognition (CVPR) Third Workshop on NAS.
- 2021, Outstanding MindSpore Developer.
- 2020, Outstanding Dissertation, Northwest A&F University.
- 2020, Outstanding Graduate, Northwest A&F University.
- 2017, President’s Scholarship, Northwest A&F University.
- 2016, National Scholarship, Northwest A&F University.
📝 Publications
Conference papers, workshop papers, technical reports, and blog publications.
-
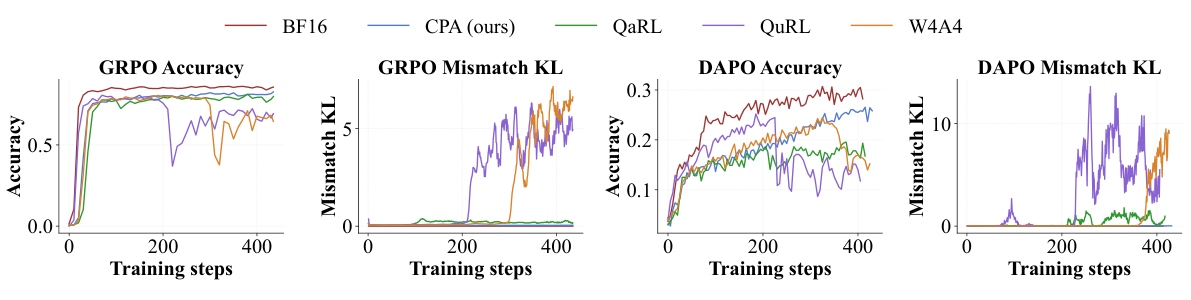 CPA: Efficient and Stable FP4 RL Training via Cross-Precision AlignmentNeurIPS 2026.
-
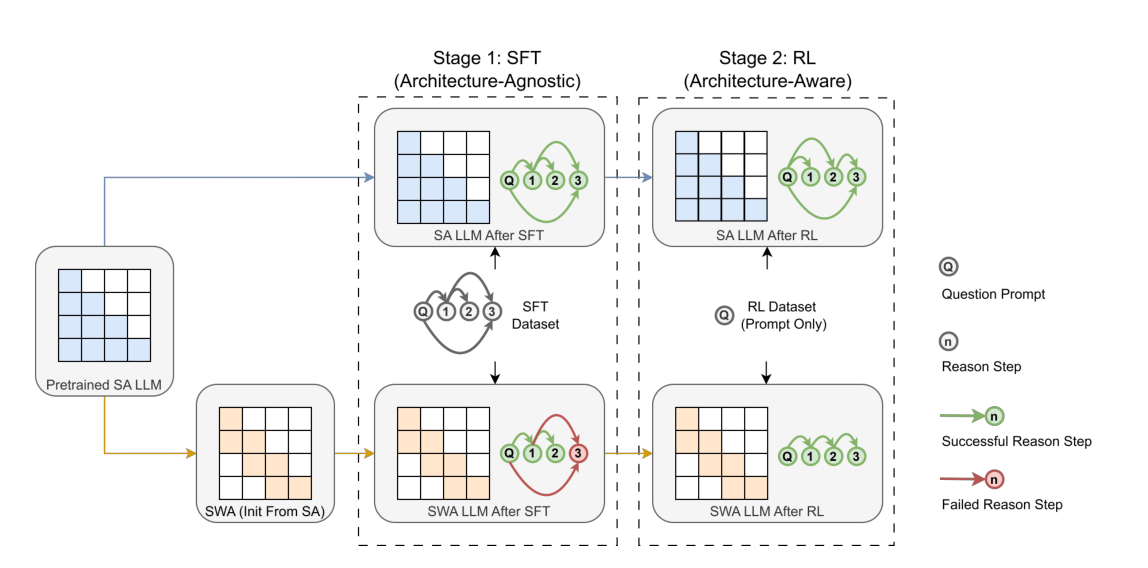 Architecture-Aware Reinforcement Learning Makes Sliding-Window Attention Competitive in Math ReasoningIn EMNLP 2026 Main Conference.
-
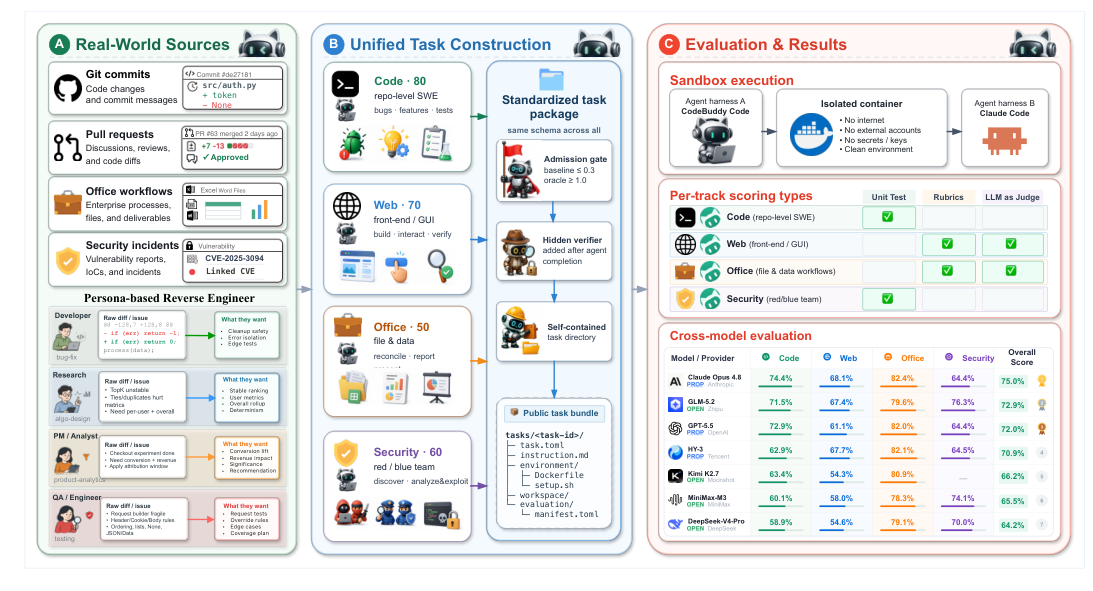 Tencent WorkBuddy Bench: A Multi-Domain Coding-Agent Benchmark with Contamination-Resistant Task ConstructionTechnical report, 2026.
-
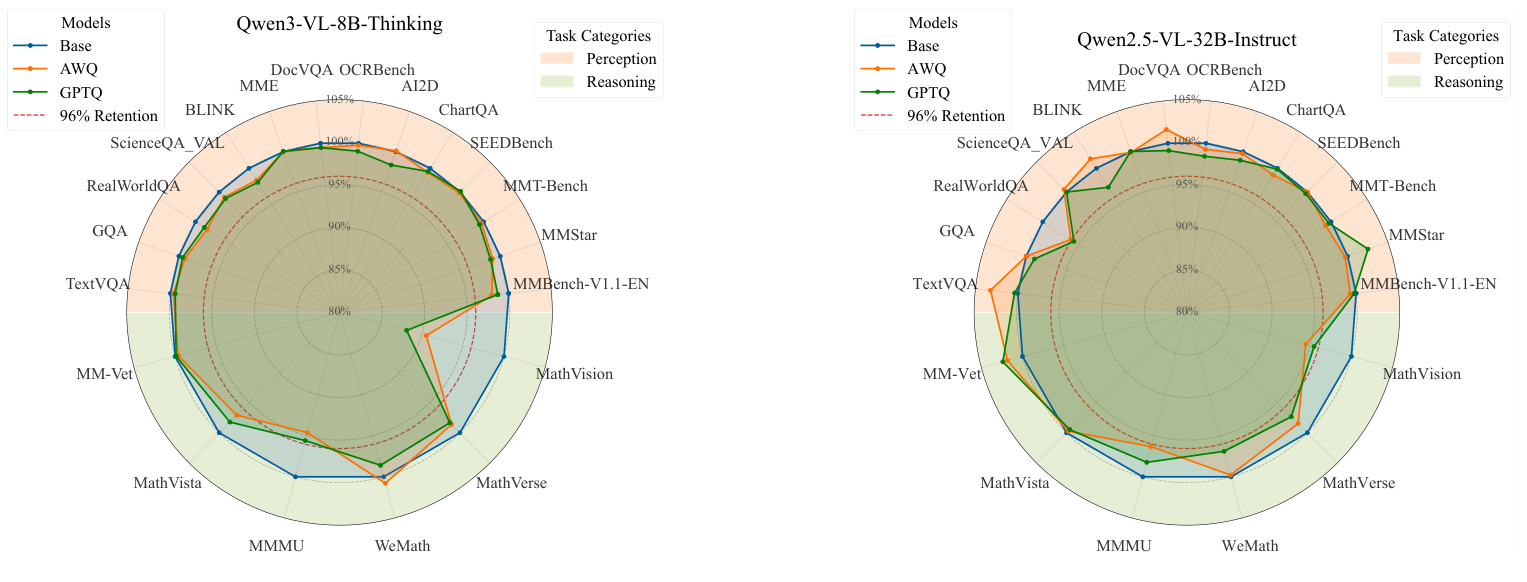 An Empirical Study of Reasoning Degradation in Quantized Multimodal Large Language ModelsACM MM 2026.
-
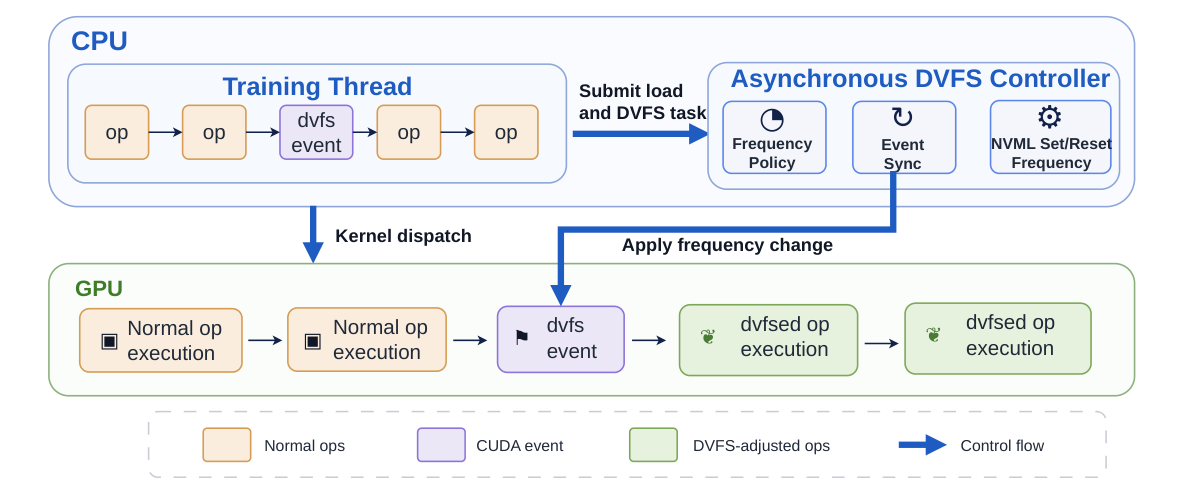 GreenMoE: Exploiting Dynamic Load Imbalance for Energy-Efficient Long-Context MoE TrainingICML 2026 AdaptFM Workshop.
-
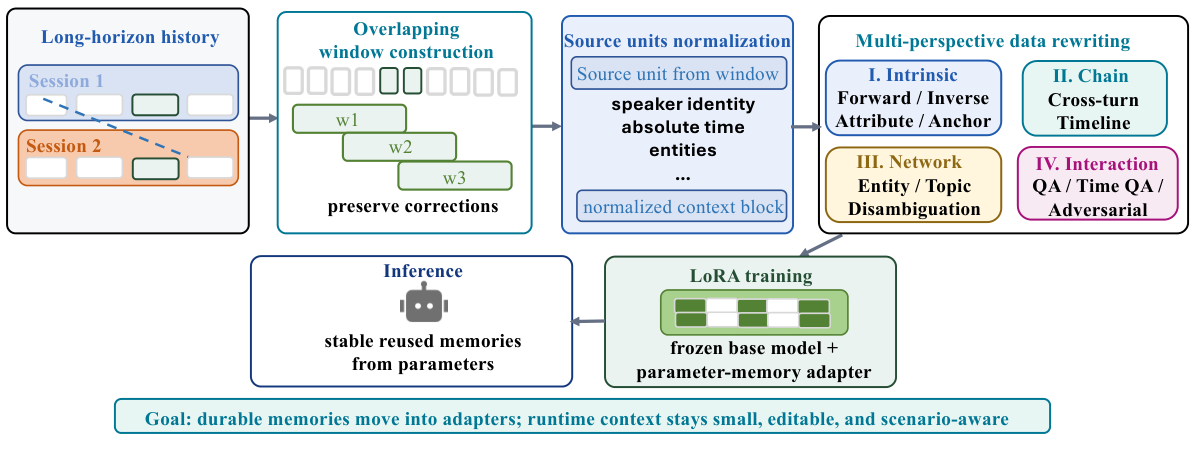 Parameters as Agentic Memory: Internalizing Long-Horizon Memories for Efficient LLM AgentsICML 2026 AIWILD Workshop.
-
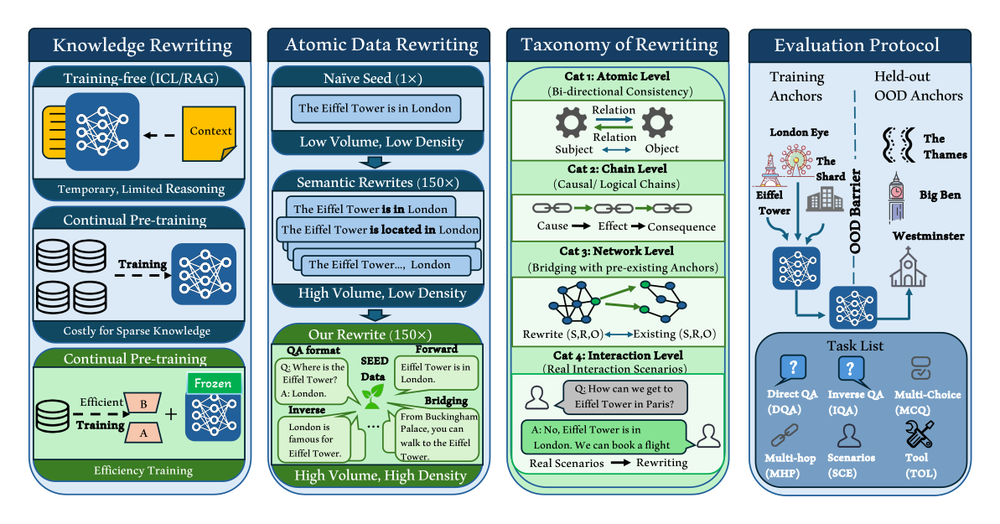 Enhancing Knowledge Injection with Surrounding Backgrounds in Continual Training LLMsICML 2026 FoGen Workshop.
-
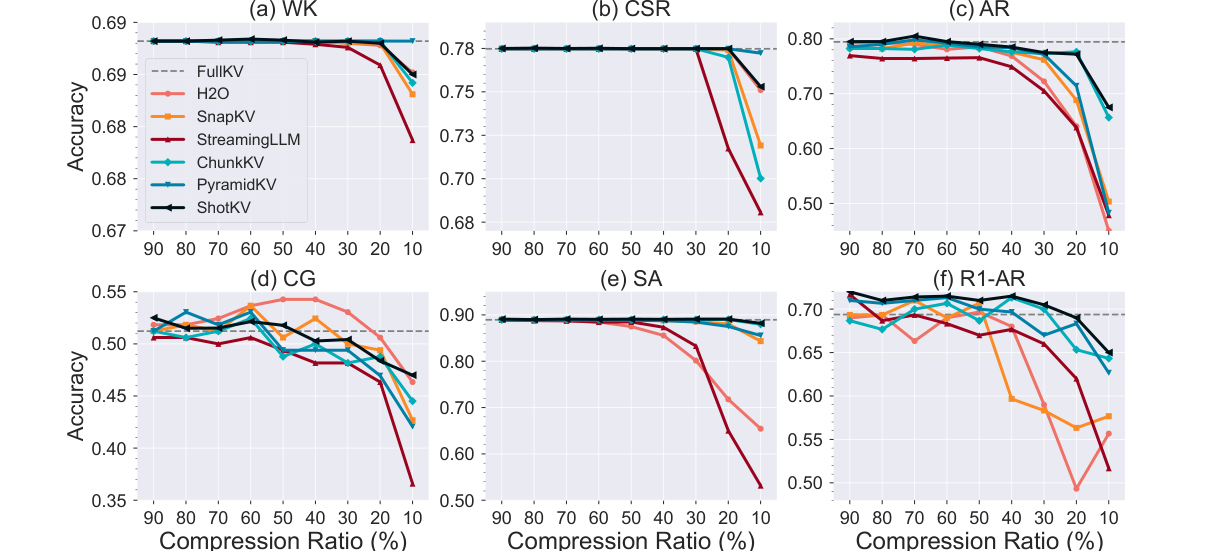 Semantic Integrity Matters: Benchmarking and Preserving High-Density Reasoning in KV Cache CompressionIn ICML 2026.
-
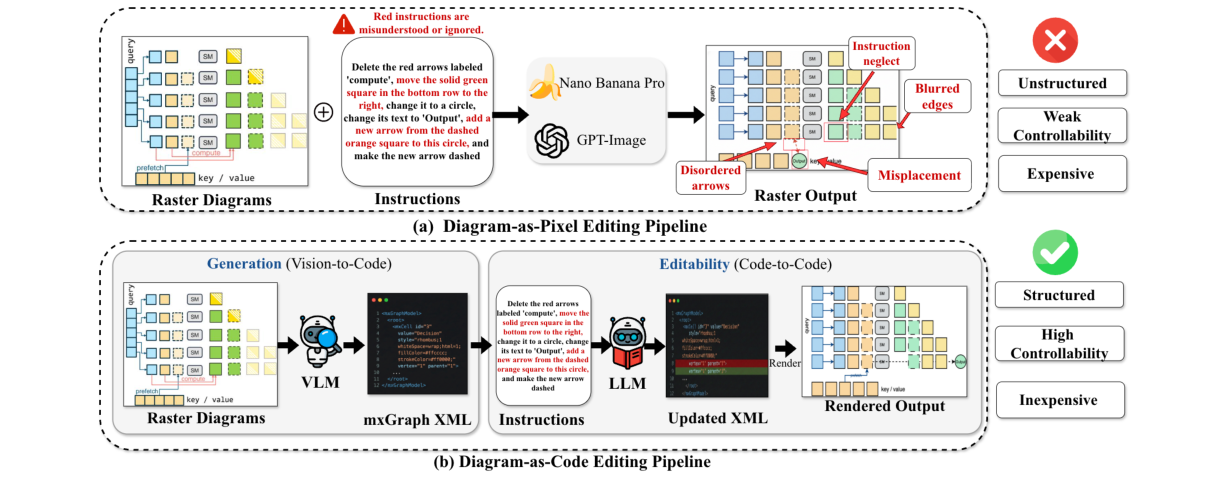 VCG-Bench: Towards A Unified Visual-Centric Benchmark for Structured Generation and EditingIn ICML 2026.
-
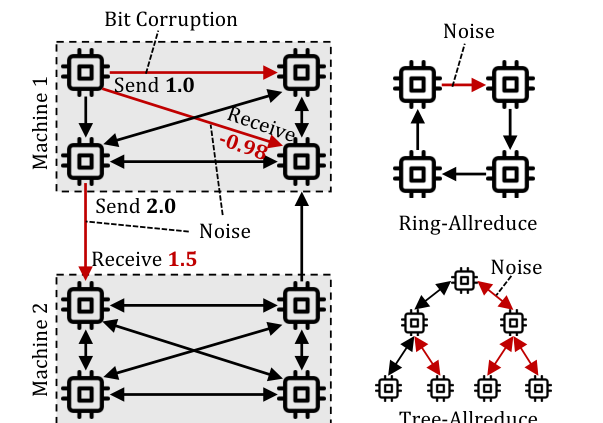 Identifying and Mitigating Errors in Gradient Aggregation of Distributed Data Parallel TrainingIn ICML 2026.
-
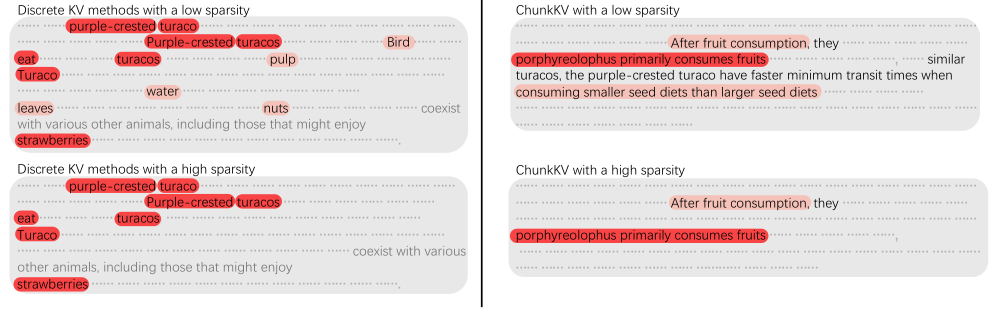 ChunkKV: Semantic-Preserving KV Cache Compression for Efficient Long-Context LLM InferenceNeurIPS 2025.
-
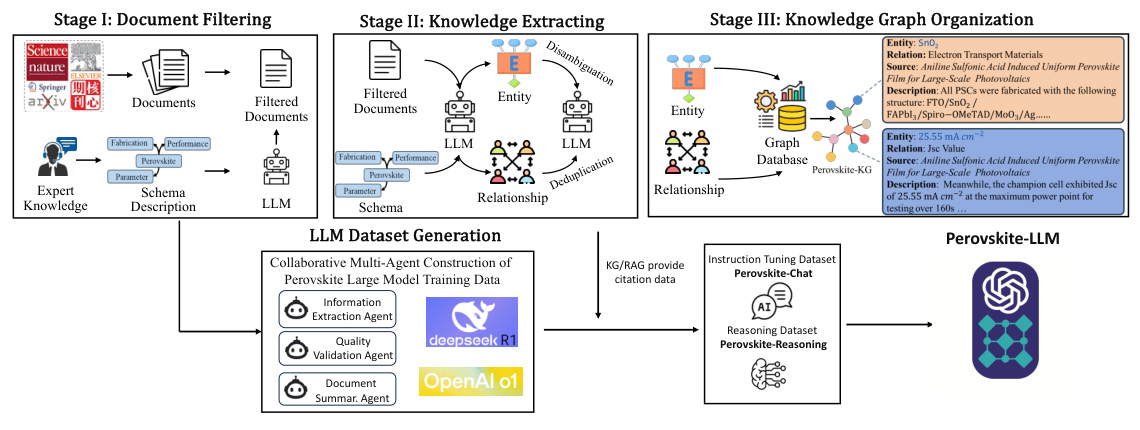 Perovskite-LLM: Knowledge-Enhanced Large Language Models for Perovskite Solar Cell ResearchEMNLP 2025 Findings.
-
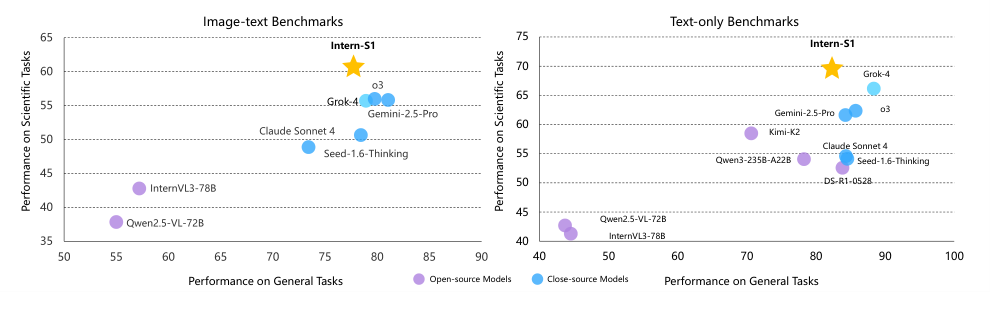 Intern-S1: A Scientific Multimodal Foundation ModelTechnical report, 2025.
-
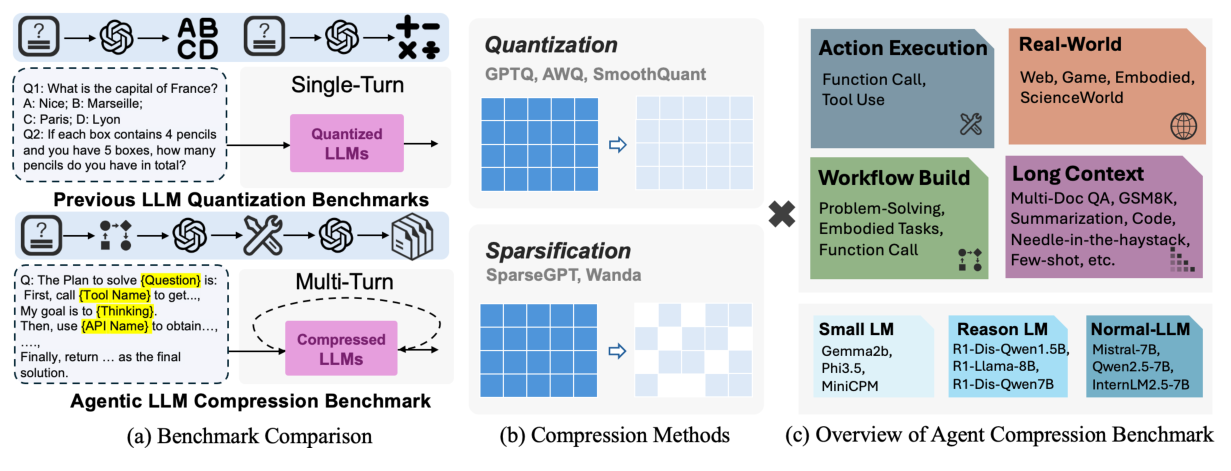 Can Compressed LLMs Truly Act? An Empirical Evaluation of Agentic Capabilities in LLM CompressionIn ICML2025.
-
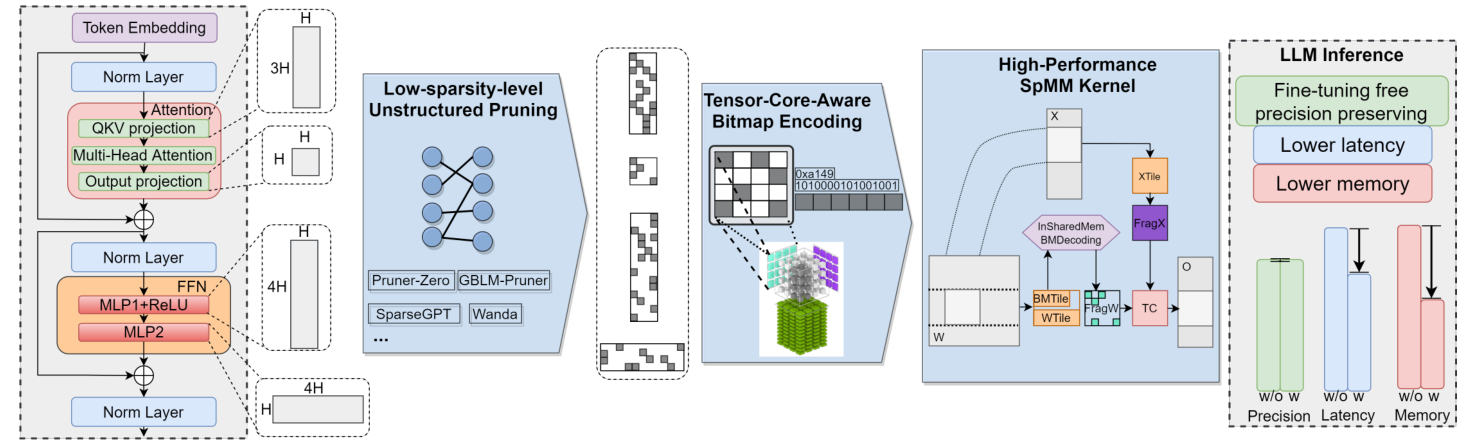 SpInfer: Leveraging Low-Level Sparsity for Efficient Large Language Model Inference on GPUsIn EuroSys2025, Best Paper.
-
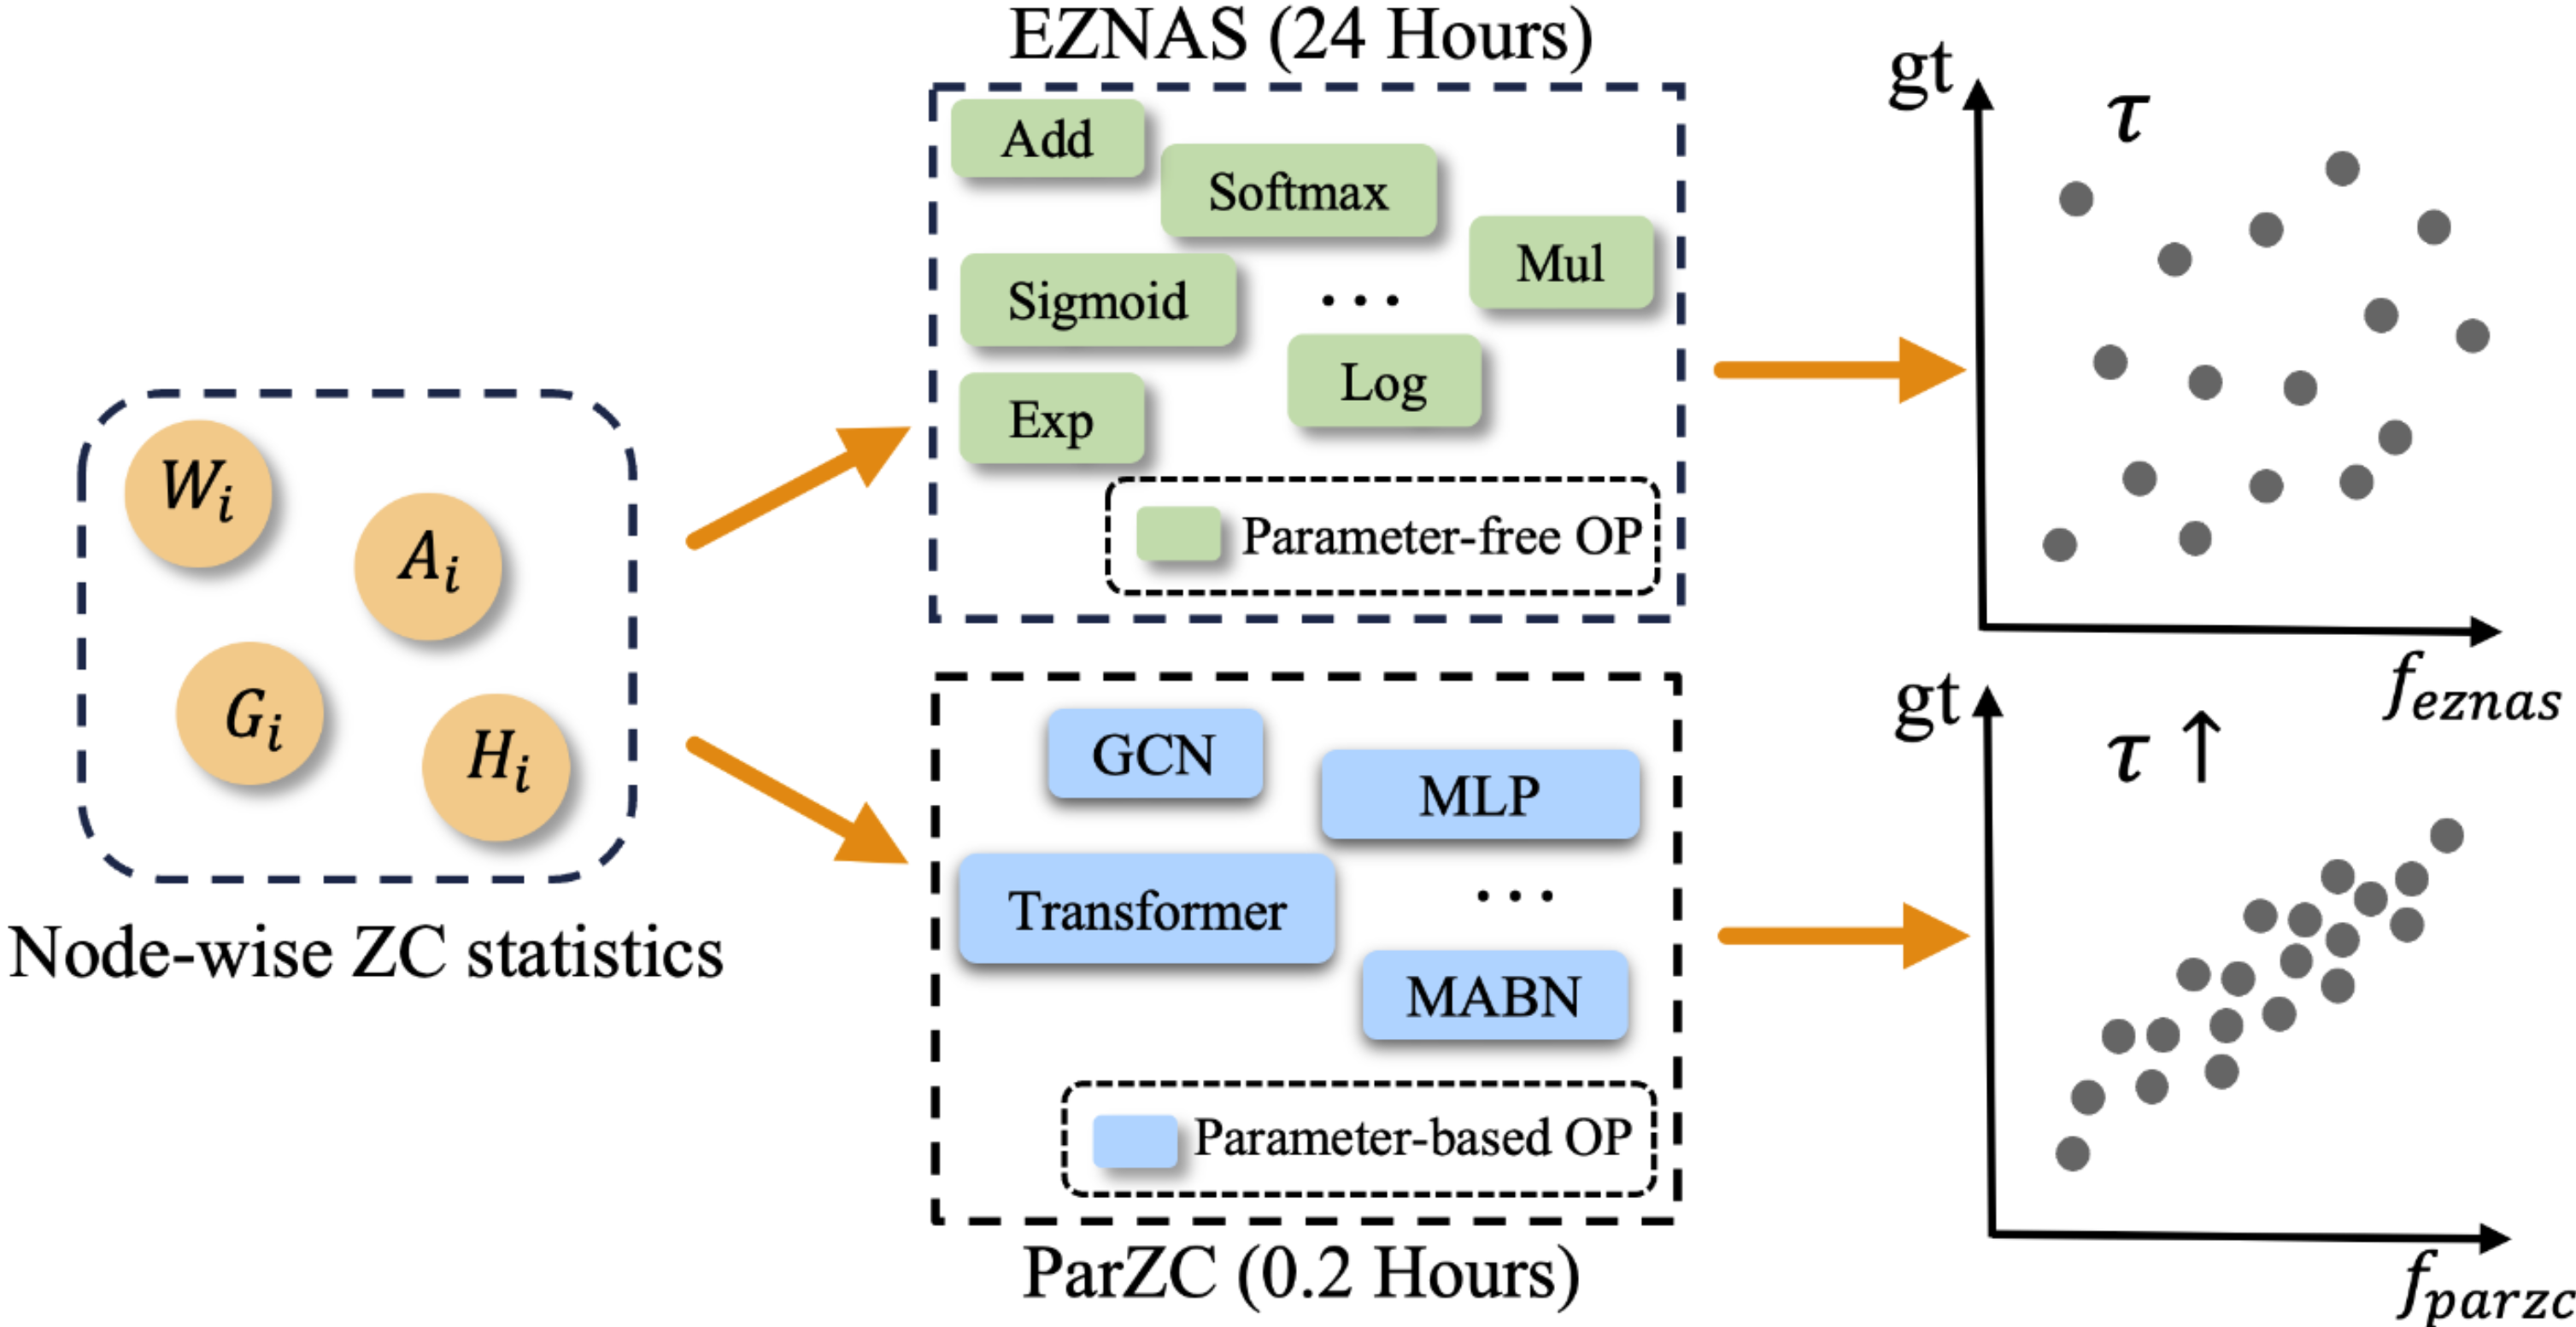 ParZC: Parametric Zero-Cost Proxies for Efficient NASIn AAAI2025, Oral.
-
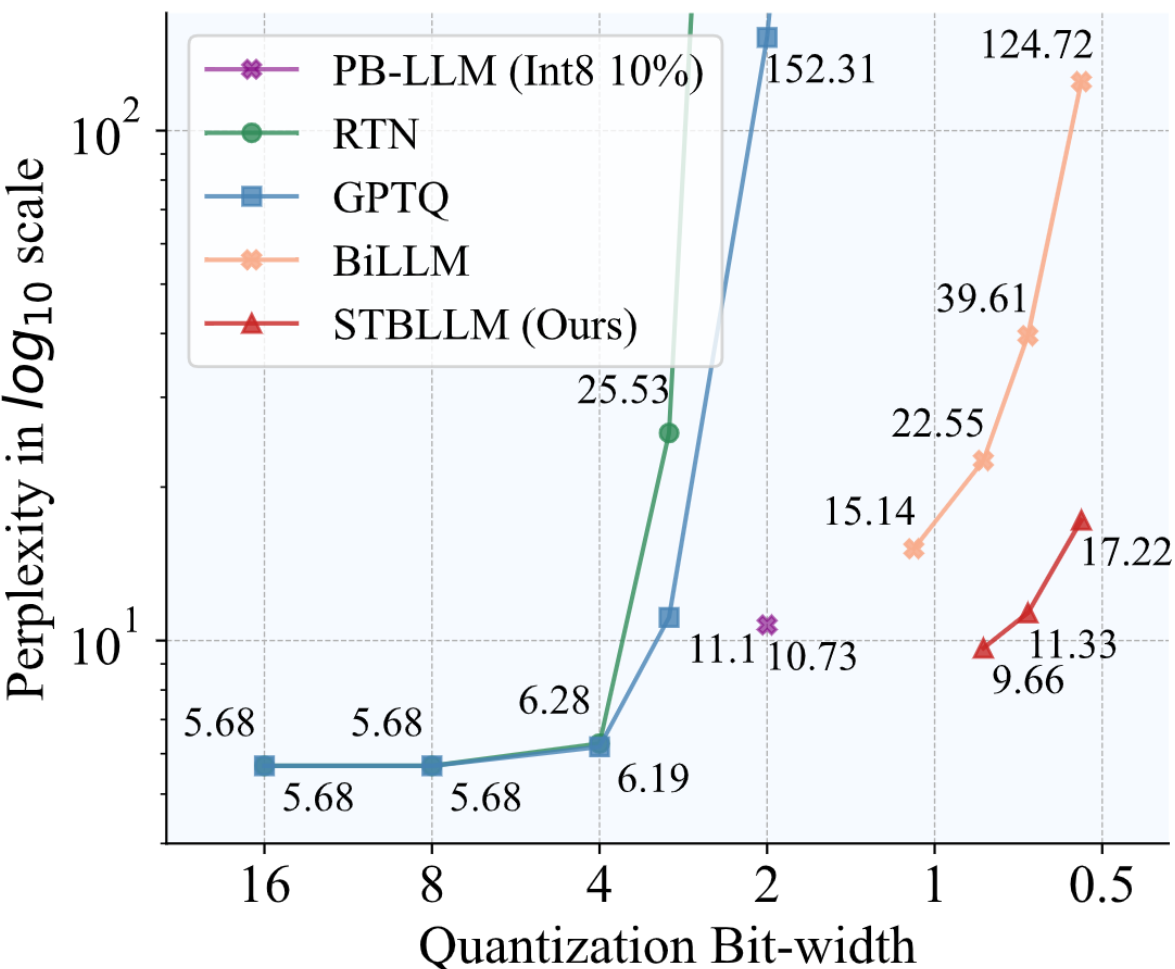 STBLLM: Breaking the 1-Bit Barrier with Structured Binary LLMsIn ICLR2025.
-
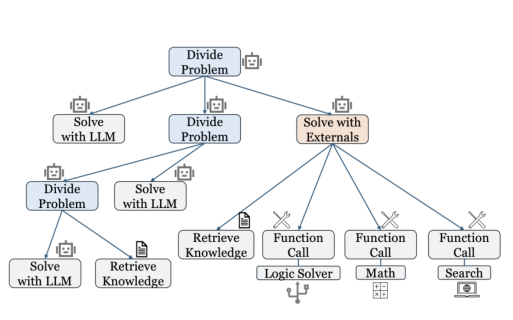 The Lottery LLM Hypothesis, Rethinking What Abilities Should LLM Compression Preserve?ICLR 2025 Blogpost, Oral.
-
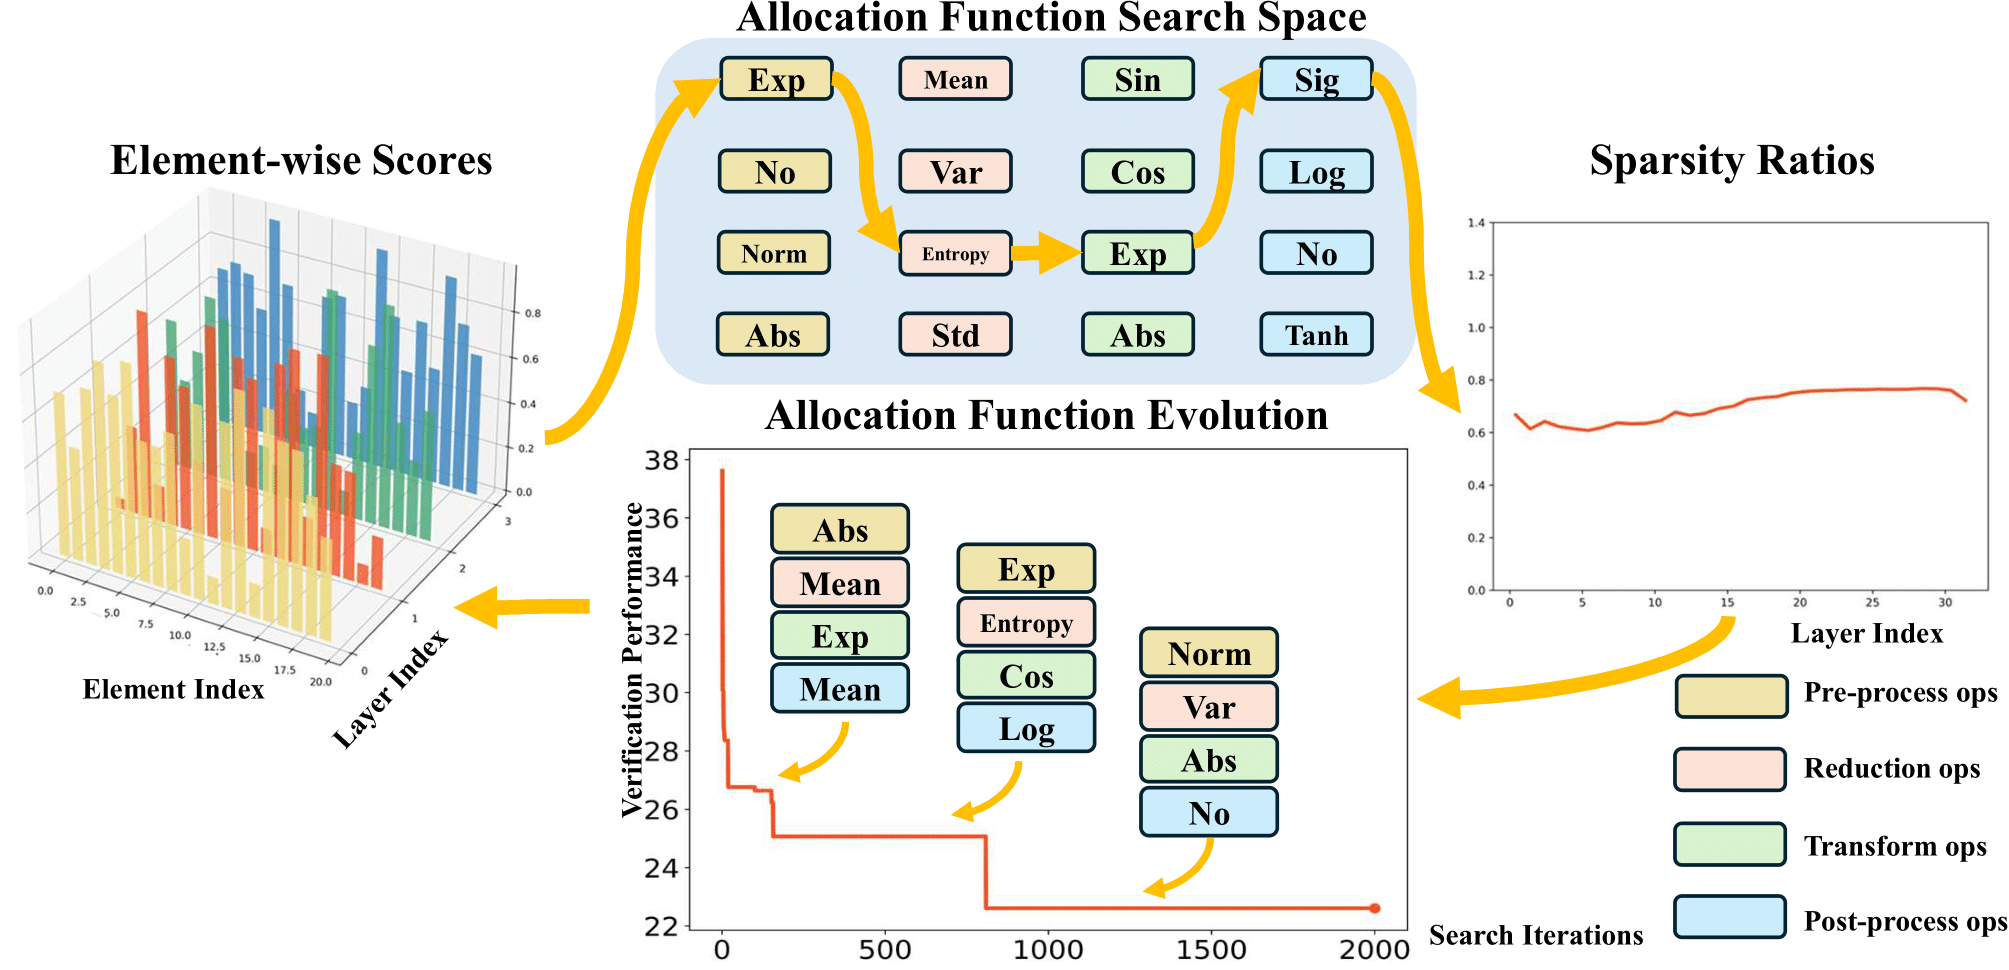 Discovering Sparsity Allocation for Layer-wise Pruning of Large Language ModelsIn NeurIPS 2024.
-
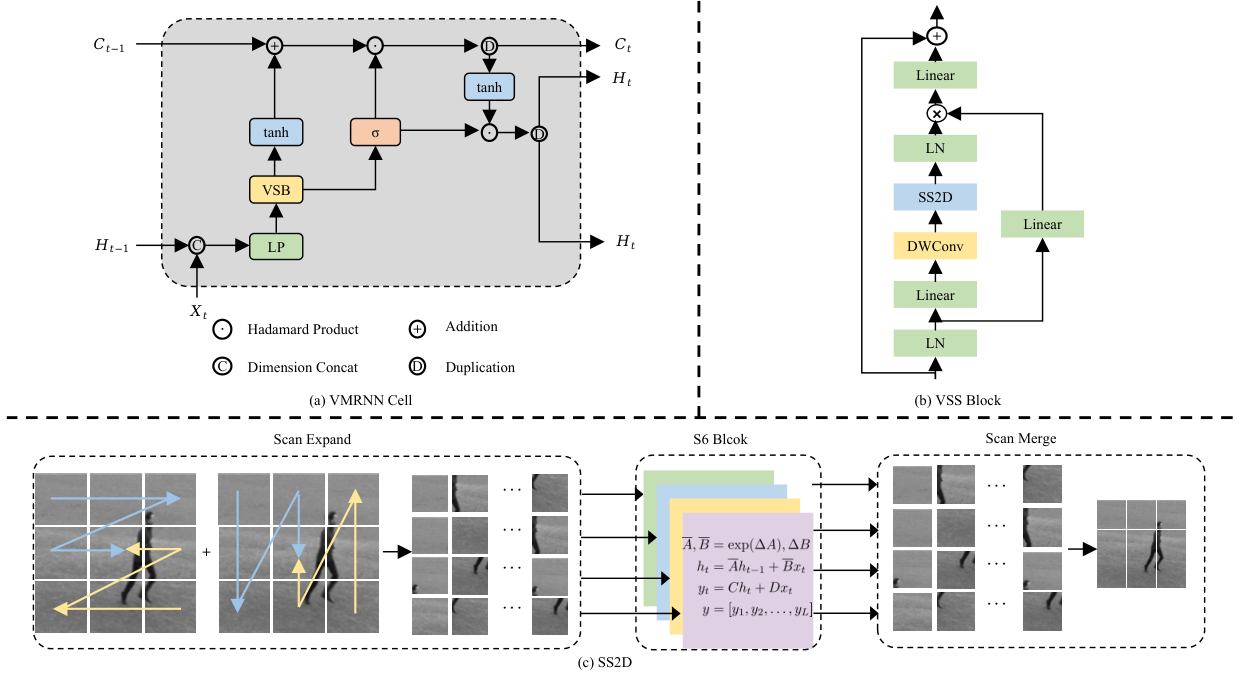 VMRNN: Integrating Vision Mamba and LSTM for Efficient and Accurate Spatiotemporal ForecastingPreprint, 2024.
-
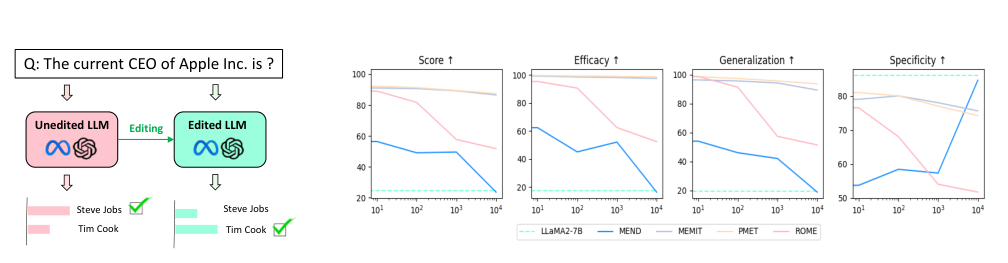 Should We Really Edit Language Models? On the Evaluation of Edited Language ModelsIn NeurIPS 2024.
-
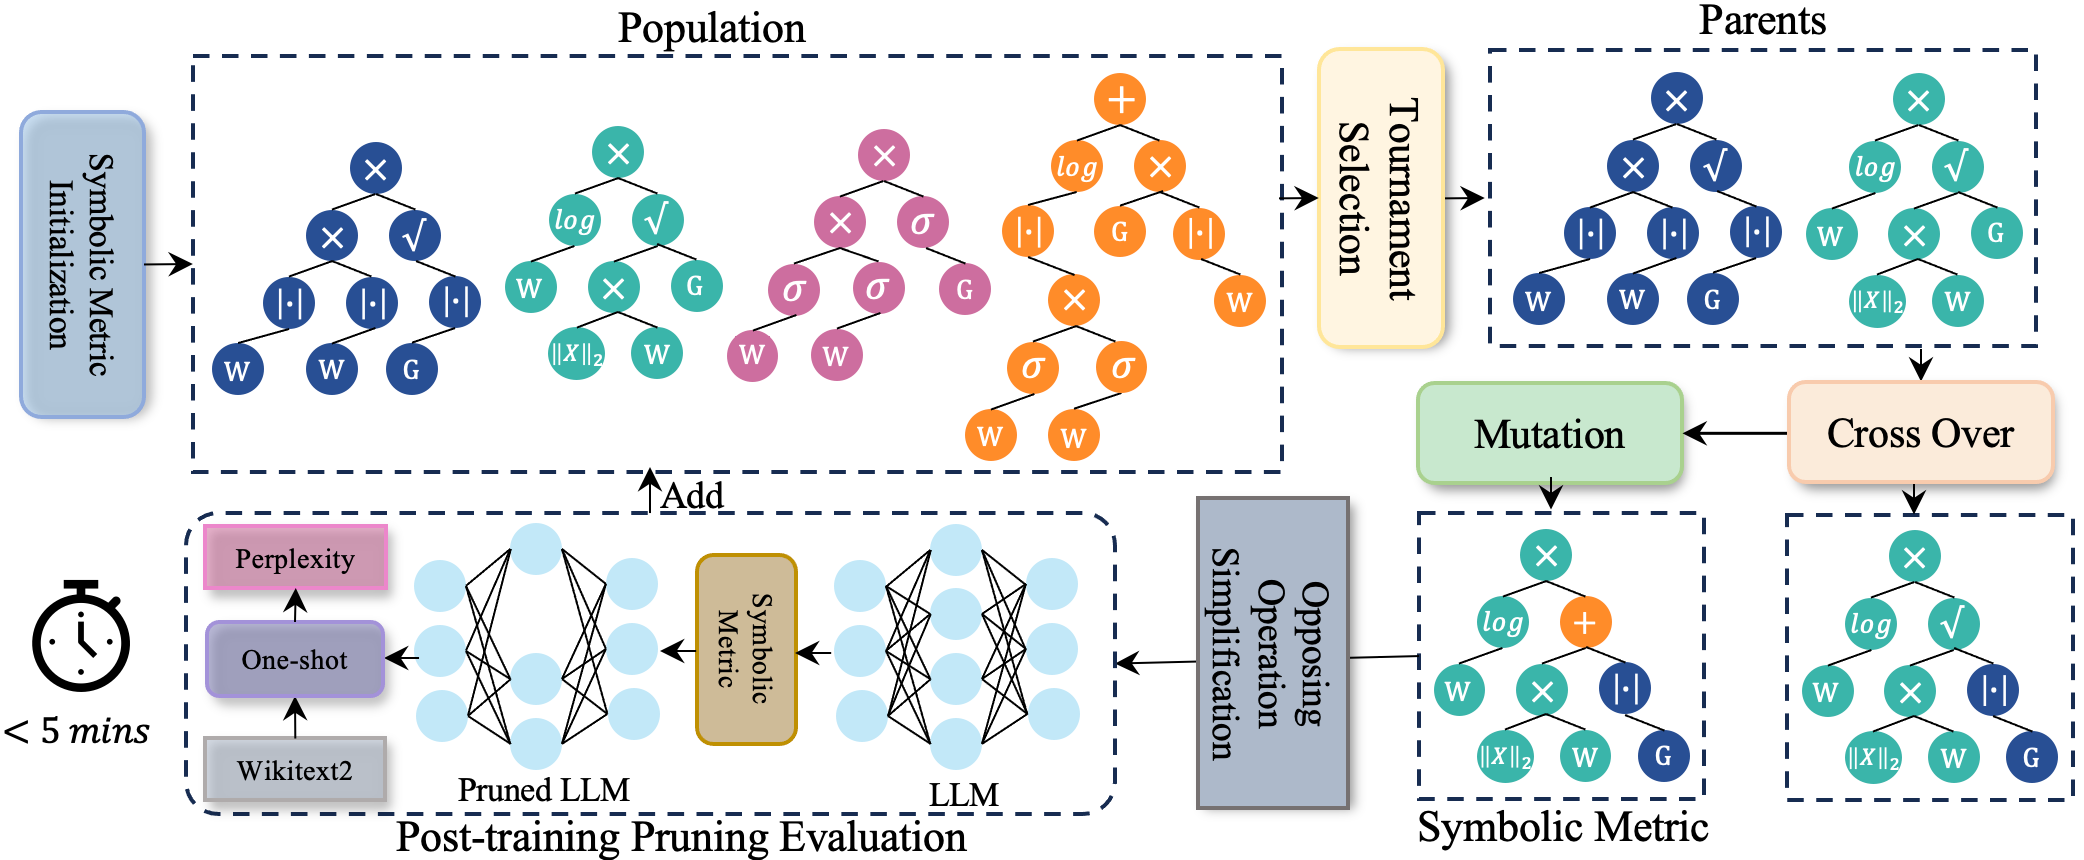 Pruner-Zero: Evolving Symbolic Pruning Metric From Scratch for Large Language ModelsIn ICML 2024.
-
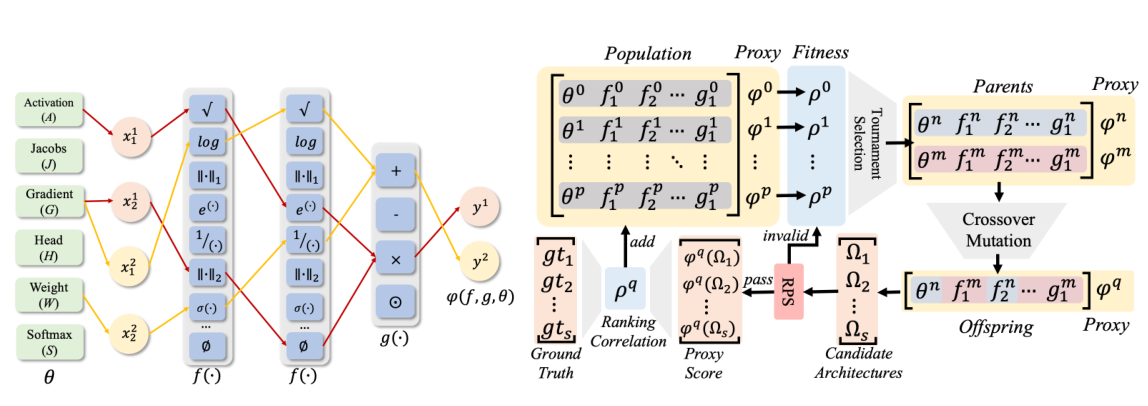 LPZero: Language Model Zero-cost Proxy Search from ZeroEmpirical Methods in Natural Language Processing (EMNLP), 2024.
-
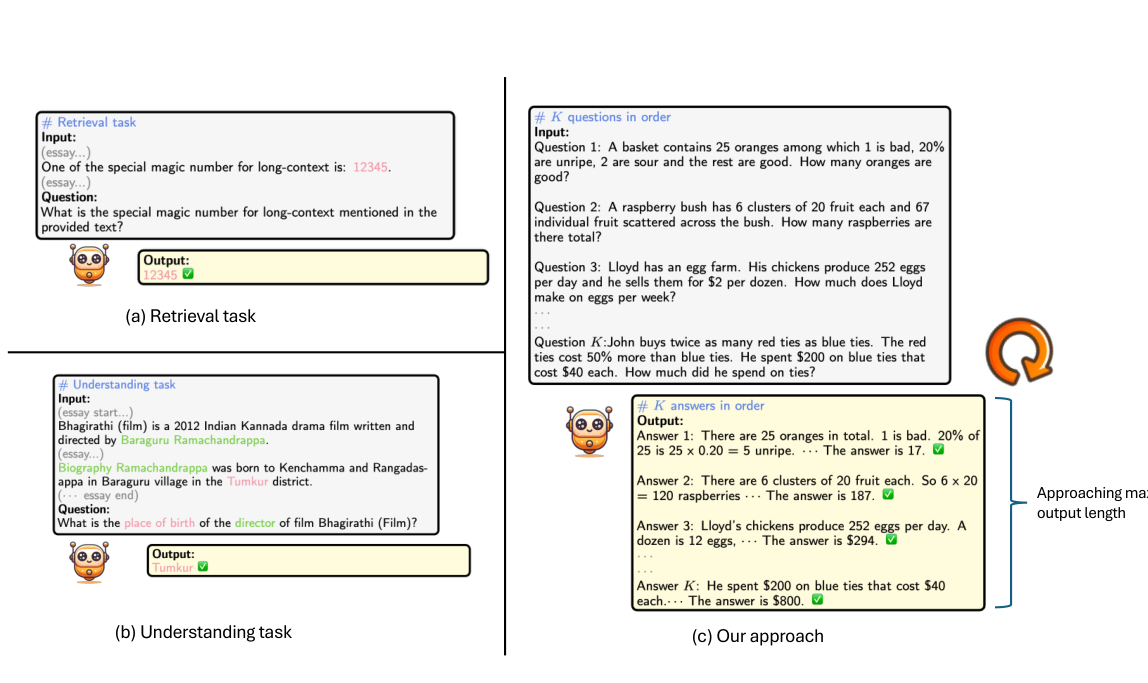 LongGenBench: Long-context Generation BenchmarkIn EMNLP 2024.
-
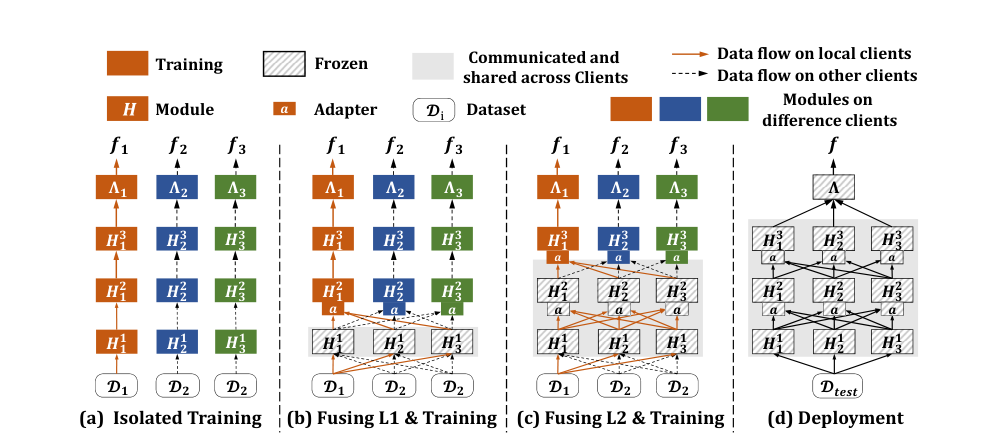 FuseFL: One-Shot Federated Learning through the Lens of Causality with Progressive Layer FusionIn NeurIPS Spotlight 2024.
-
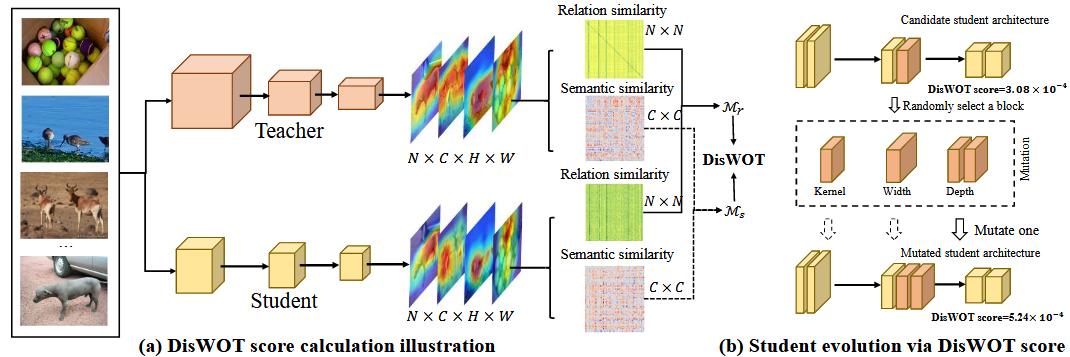 DisWOT: Student Architecture Search for Distillation without TrainingIn CVPR 2023.
-
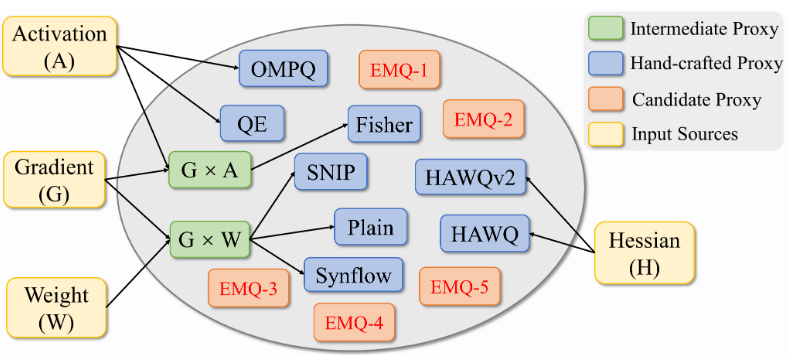 EMQ: Evolving Training-free Proxies for Automated Mixed Precision QuantizationIn ICCV 2023.
-
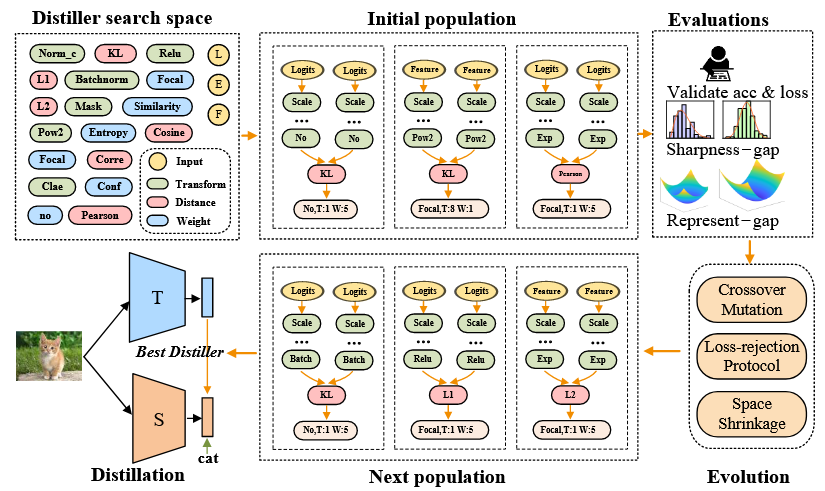 Kd-zero: Evolving knowledge distiller for any teacher-student pairsIn NeurIPS 2023.
-
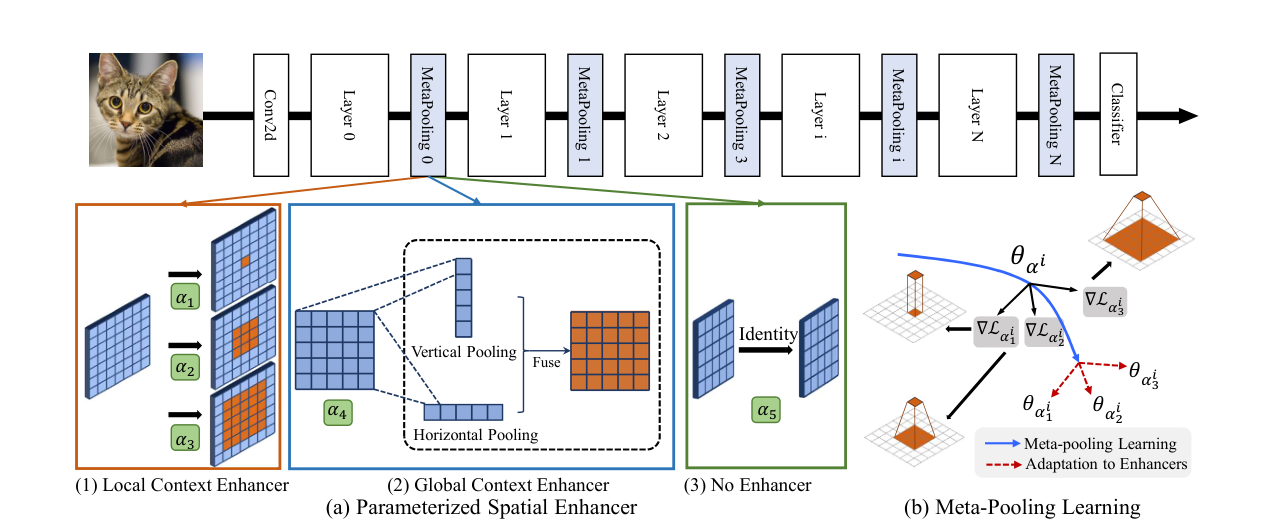 Progressive Meta-Pooling Learning for Lightweight Image Classification ModelIn ICASSP 2023.
-
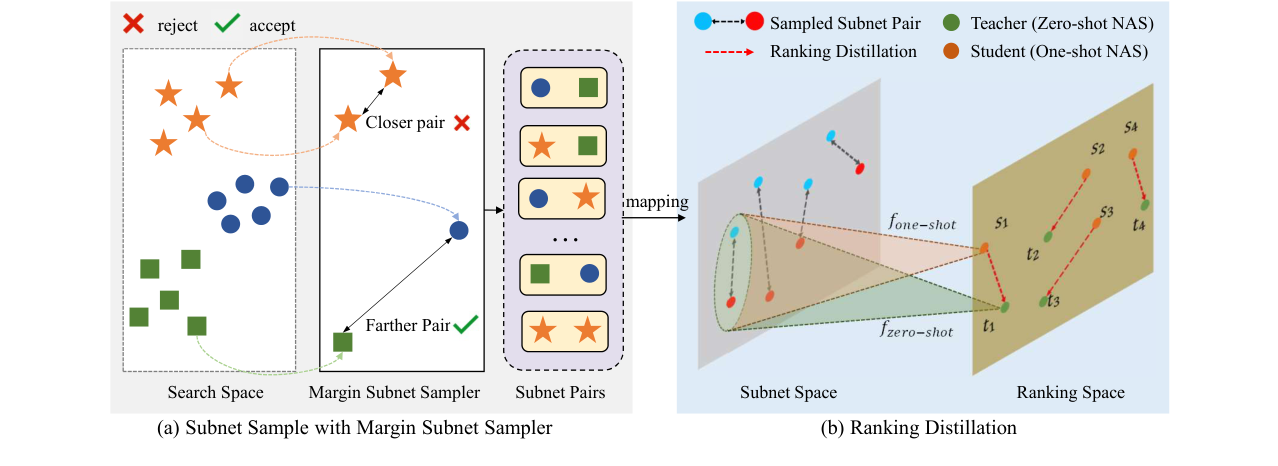 RD-NAS: Enhancing One-shot Supernet Ranking Ability via Ranking DistillationIn ICASSP 2023.
-
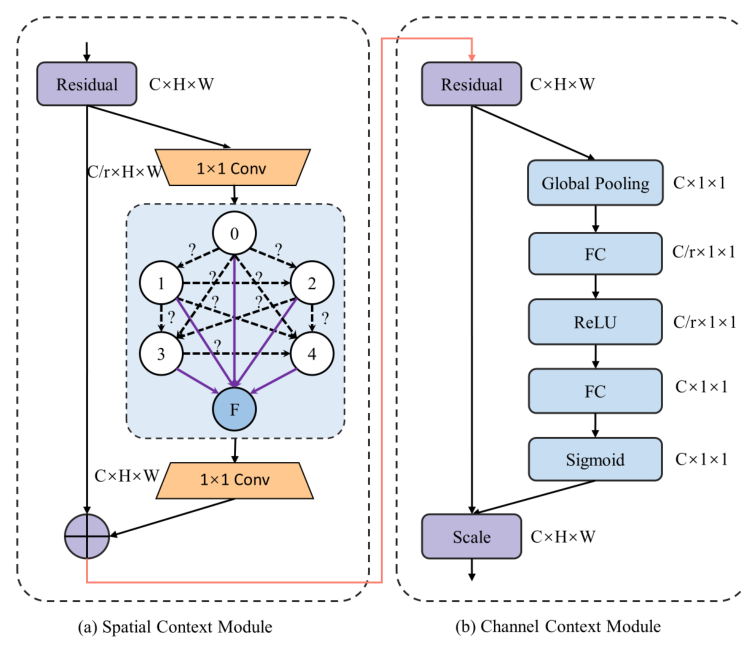 AutoRF: Auto Learning Receptive Fields with Spatial PoolingIn MMM 2023.
-
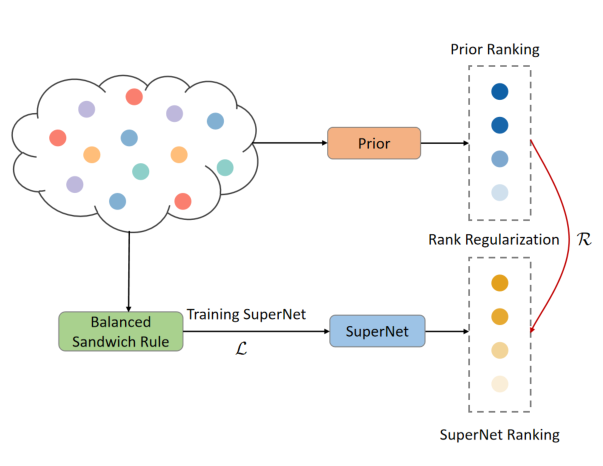 Prior-Guided One-shot Neural Architecture SearchIn CVPR Workshop 2022.
-
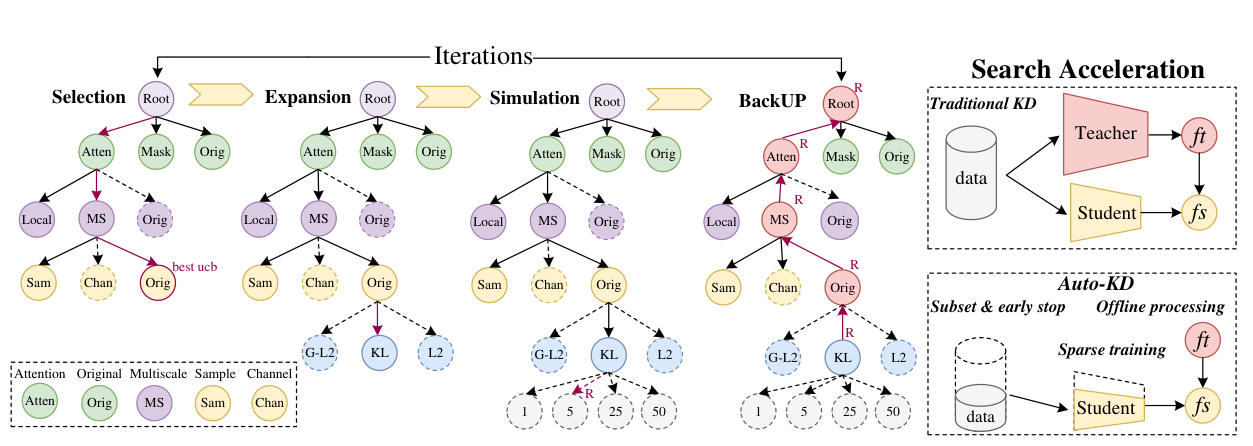 Automated Knowledge Distillation via Monte Carlo Tree SearchIn ICCV 2023.